1Change first
No source in the answer
6 in 10 answers
Eva ties what your users need to the code behind it. When an evaluation falls short, the result points at the code, and Eva drafts the pull request for your team to review. When you ship, Eva measures again, so you know whether the change worked and what to change next.
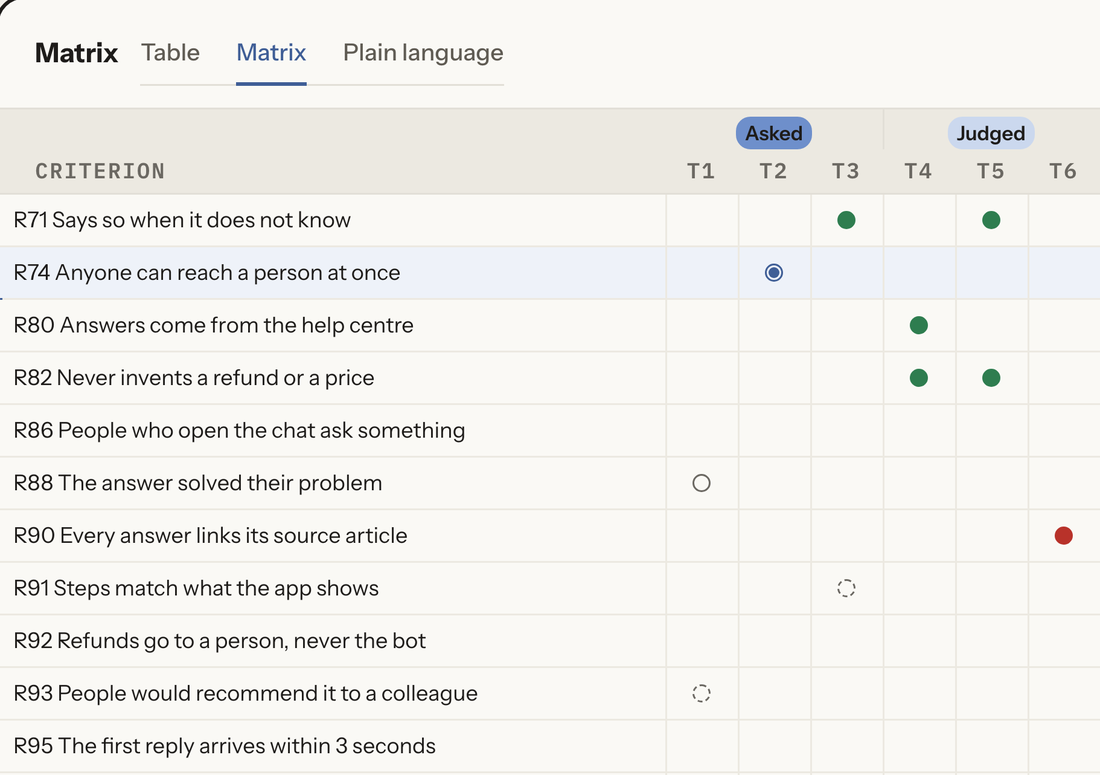
You want to build the best product for your users. So you ship changes every week, talk them through with your team, and ask your users what they think. But what you learn ends up everywhere: in tickets, in Slack, in a survey, in someone's head. Nothing points at anything, the same question gets asked twice, and answers come in that never turn into a change. Eva connects what you know about your product with what you learn from evaluating it, so every iteration counts.
where did the bot get this from??
"customers keep asking for the source"
"did that help?" Nobody knows.
"it just does things" · 6 of 25 positive
it booked a flight before I said yes
thumbs down 14% this week
"I stopped trusting it without a source"
pass the docs to the prompt
"is the price it shows final?" asked 9 times
the version before. Or after?
answer was wrong?
41% cite a source
3 pieces of evidence → answer.ts → PR #142 → 41% → 78%
survey + ticket → agent/tools.ts → PR #151 → 6 → 19 of 25
2 pieces of evidence → escalate.ts → no change yet → 18% guesses
9 Slack messages → no criterion yet → to your designers
Eva judged 120 → summarize.ts → no change needed → met twice
diary, day 4 → chat/memory.ts → PR #158 → 52% → 96%
ticket + survey → agent/tools.ts → PR #151 → 9 → 0 unasked
Eva judged 120 → report/prompt.ts → PR #160 → 30% → 88%
12 of 25 asked → app/chat → waiting → too few answers
Eva measures the same criteria before and after every change, and keeps each one with the evidence behind it, the change it led to, and what that change did. Each release adds a round, and each round starts from everything the last one found. Two releases later, your team can still say why the search was changed and whether users noticed. That record is what Eva is. The pull requests are what it produces.
Your part of the setup is the first commit. Everything after that arrives as pull requests your team can read, comment on and merge.
Eva never merges its own work and never pushes to your main branch.
Example: a support chatbot that answers your customers' questions using your help pages. Eva works the same way for search, writing tools, agents and any other AI feature.
With Eva: Eva keeps every change: what was changed, why, and whether it helped your users.
Most answers don't show a source
The chatbot finds the right help page, but answers without reading the page
Use the help page in the answer PR #142
Answers with a source: 4 in 10 → 8 in 10
With Eva: Eva measures every criterion your team wrote down and shows which ones are furthest from their pass mark, so you know what to change first.
With Eva: Eva points each result at the part of your code that produced it, so nobody has to guess.
With Eva: After every change, Eva measures all your criteria again, so you see side effects before your users do.
The chatbot answers from memory
The chatbot reads your help page first
The source is there now. Nothing else got worse.
With Eva: Eva suggests the actual change, ready for you to review.
EvaMost answers don't show a source. The chatbot finds the right help page, but answers without reading the page. I've made a small change so the chatbot reads the help page first.
PR #142
Looks good, merging.
EvaA week later: 4 in 10 → 8 in 10 answers show their source. Nothing else got worse.
With Eva: Eva judges every answer against your criteria, and asks your users whether it helped.
How do I export my data?
Go to Settings → Export.
Did this help?With Eva: Write it down as a criterion once. Eva measures it again after every change.
Someone changed how the chatbot searches. In the next round, two judged answers showed another customer's email. The criterion went to not met, and Eva proposed limiting the search to the customer who is asking.
A team ships an AI support assistant that answers from their docs. Users start asking where the answers come from, because the assistant never links to its source.
A ticket about an unsourced answer lands in a spreadsheet with 200 others.
Eva checks every answer. Only 41% link to the docs page they used. The team asked for 60%.
The team meets to guess. A developer spends a day reading code.
The result points straight to the file that builds the answer.
Someone adds a line to the prompt and hopes for the best.
Eva writes the change as a pull request that already passes your checks. A developer reviews it and merges.
Nobody knows. Maybe the complaints stop. Maybe the next one arrives in two weeks.
The next round measures the same thing again. Now 78% link to their source.
Product teams with an AI feature in front of real users, who want to know whether it does what those users need, and what to change when it doesn't.
Eva is built for products with an AI feature. The questions to your users work for the rest of the product too; the judging of answers applies to the parts that use a model.
Eva uses AI models to judge each answer against the criteria your team agreed on. Questions that only your users can answer, such as whether an answer solved their problem, are asked to your users instead.
No. Eva proposes a change for each criterion that isn't met. Code is written only for the changes you accept, and they arrive as one pull request that a person on your team merges.
No. An audit tells you where you stand once. Eva keeps the criteria, the evidence and the changes from every round, so the next release is measured against what you already know. The longer it runs, the better it knows your product and your users.
No. Pull requests go to your developers. When what users say raises something no criterion covers yet, such as a topic they keep bringing up or a value that is missing, Eva puts it in front of your designers as a new topic. It does not turn that into code.
Eva keeps what it works out from your code, such as the map of your product's parts, and adds it to your own repository in a folder called .eval/ so you can read it. Your AI's answers are kept only as a fingerprint by default. You can choose to keep the text.
Eva is in pre-launch and opening to a small group of teams first. Request access below and tell us what you want to evaluate. We'll get back to you.
That is the finding of a study led by Willem van der Maden, co-founder of Eva, published at ACM CHI 2026. Research has pointed the same way for 20 years: finding problems is easier than knowing what to change. Eva is built to close that gap.
Most evaluation of AI products is a spreadsheet of opinions, or a benchmark that measures something other than what users need. Neither tells you what to change. We're building Eva so that every result can be traced to the code behind it, and every change is measured again.
Co-founder · Researcher at the IT University of Copenhagen
Researching and publishing on evaluation in AI design since 2019.
Co-founder · Engineering
Developed the method behind Eva at the IT University of Copenhagen, and now builds the product.
Eva is in pre-launch. Tell us a little about your product and what you want to know about it. We'll get back to you.